
Agent observability is the practice of recording every step an AI agent takes (each LLM call, tool call, retry, and subagent) as structured trace data you can inspect, query, and evaluate. It exists because agents are non-deterministic: the same input can produce a different path, so the only way to know what happened is to have recorded it.
What is agent observability?
Agent observability means capturing an agent's full execution as traces and spans, then using that record to explain why a run produced the output it did. A traditional service is observable when you can answer "is it up, how fast, how often does it error". An agent needs a different set of answers: what did it decide, which tool did it reach for, what came back, why did it loop, and did the run actually accomplish the task.
Non-determinism. Run the same prompt twice and you get two different paths. A stack trace from one failure tells you nothing about the next. You need the distribution, not a single sample.
Silent failure. An agent that fails rarely throws. It returns a confident, wrong answer with HTTP 200. Error rate stays flat while the product gets worse.
Depth. A ten-minute run produces hundreds or thousands of spans across subagents, tool calls, and retries. The interesting event is somewhere in the middle, and you do not know its name in advance.
Why logs and APM aren't enough for AI agents
Both work. Neither is sufficient.
Logs have no structure across a run. You get a flat stream where the relationship between a planning call, the tool it triggered, and the retry that followed exists only in your head. Reconstructing one run means grepping a request ID and reading upward, and that stops working once subagents run concurrently.
APM measures the wrong dimensions. An agent's failure modes are semantic: it asked the user something it had already been told, it called the same tool eleven times, it gave up. None of those move a p99 latency chart. A run that returns garbage in 400ms looks healthier than a correct run that took 40 seconds.
Neither carries cost. Tokens and dollars are first-class facts about a run, and getting them per run rather than per call is its own problem (cost tracking).
Core concepts: traces, spans, sessions, and evals
Traces: one agent run, end to end
A trace is one execution of your agent, from the request that started it to the response it returned. It is the unit you reason about: "this run cost $0.42, took 38 seconds, made 61 LLM calls, and returned the wrong invoice number" is a statement about a trace. Cost, tokens, duration, status, user, and metadata all attach to it.
Spans: one step inside a run
A span is a single operation within a trace: an LLM call, a tool call, a retrieval, a function you named. Spans nest, so a subagent is a span containing the spans it produced, and the tree records the agent's control flow. Type matters: an LLM span carries model, prompt, completion, token counts, and cost; a tool span carries arguments in and result out. Typing them correctly is what makes "show me every failed tool call last night" a query rather than a text search.
Sessions: many runs, one conversation
A session groups traces that belong together: a multi-turn chat, a task resumed across days, an agent that wakes on a schedule. Without it, turn 7 is an orphan run and the bug that started at turn 2 is invisible.
Evals: measuring a change instead of guessing
An eval runs your agent over a fixed set of inputs and scores the results. Tracing tells you something is wrong on one run; an eval tells you whether your fix works in general. Production traces are where eval datasets come from, because the inputs that broke your agent are better test cases than any you would invent.
What to instrument in an AI agent
Start with these, in order:
- Every LLM call. Model, provider, full prompt, full completion, token counts, cost, latency, finish reason. Non-negotiable: it is where the agent's decisions live.
- Every tool call. Name, arguments, return value or error. Most agent bugs are tool bugs: bad arguments, a schema the model misread, an API that returned an empty list the agent treated as fact.
- The top-level run. One span wrapping the whole thing, carrying user ID, session ID, and whatever metadata you will want to group by later.
- Subagent boundaries. A span per subagent, so its work is scoped and collapsible instead of interleaved with its parent's.
- Retrieval. Query, result count, which documents came back. "The model hallucinated" is frequently "retrieval returned nothing and the model filled the gap".
- Control flow you would name in a design doc. Planning, validation, reranking, the branch that picks between two strategies.
Skip per-token streaming events, framework internals with no semantic meaning, and anything you would not read while debugging. Span volume costs storage and, more expensively, attention.
Auto-instrumentation vs manual spans
Auto-instrumentation patches the provider and framework libraries you already call, so every LLM and tool call is traced without touching your code. Broad coverage for one initialization call. The limit is that it only knows libraries someone wrote an instrumentation for, and it names spans after the library rather than after your domain.
Manual spans cost a line of code and give you names that match how you think about the agent, plus coverage for anything auto-instrumentation cannot see: a private model endpoint, a raw HTTP call, business logic between model calls.
Use both. In practice that is one initialization plus a decorator on your entrypoint:
from lmnr import Laminar, observe

Laminar.initialize()

@observe()
async def run_agent(prompt: str):
    ...  # your agent code
import { Laminar, observe } from '@lmnr-ai/lmnr';

Laminar.initialize();

export const runAgent = observe({ name: 'runAgent' }, async (prompt: string) => {
  // your agent code
});
Laminar auto-instruments the major providers and agent frameworks from that single initialize() call, and manual spans are there for the rest (integrations, manual spans).
How traces get into an observability backend
Three paths, trading setup effort against how much control you keep over the shape of the spans.
| Instrumentation SDK | Plain OpenTelemetry exporter | Proxy or gateway | |
|---|---|---|---|
| What you change | One initialize() call | Tracer, exporter, and span attributes you set yourself | The base URL your client points at |
| LLM call coverage | Automatic for supported providers | Whatever you instrument | Every call through the proxy |
| Framework spans | Automatic for supported frameworks | Manual | Not visible: the proxy sees HTTP, not your control flow |
| Works for unsupported languages | Only where an SDK exists | Anywhere OpenTelemetry exists | Anywhere |
| Sits in your request path | No | No | Yes |
| Best for | Python and TypeScript agents | Existing OTel setups, other languages | Legacy services you cannot rebuild |
The wire format is the same either way. If the backend speaks OTLP, an SDK is a convenience rather than a commitment. Laminar accepts OTLP over gRPC, HTTP/protobuf, and HTTP/JSON on both cloud and self-hosted, so an existing pipeline points at it by changing an endpoint and an auth header (OpenTelemetry setup).
How to read an agent trace
Here is where most agent observability tooling falls down. The default UI for a trace is a span tree, inherited from backend APM, and a span tree is the wrong shape for an agent.
A tree answers "what called what, and how long did each part take". That is the right question for a distributed request. For an agent the question is "what did it say, what came back, and where did it go wrong", and the tree buries that under 400 rows of nested names with the content one click away on each.
| Span tree | Transcript | |
|---|---|---|
| Optimized for | Structure and timing | Content and sequence |
| Reading an LLM turn | Click the span, open the attributes panel | Inline in the flow |
| Subagents | Nested rows, interleaved with the parent | Collapsible cards with input and output previews |
| Finding a failed tool call | Scan for the red row | Visible in sequence with its arguments |
| "How long did retrieval take" | Directly, from the waterfall | Not its job |
Neither is redundant. The tree is right for timing questions: which step dominated the 38 seconds, what ran concurrently, where the dead air is. The transcript is the right default for everything else.
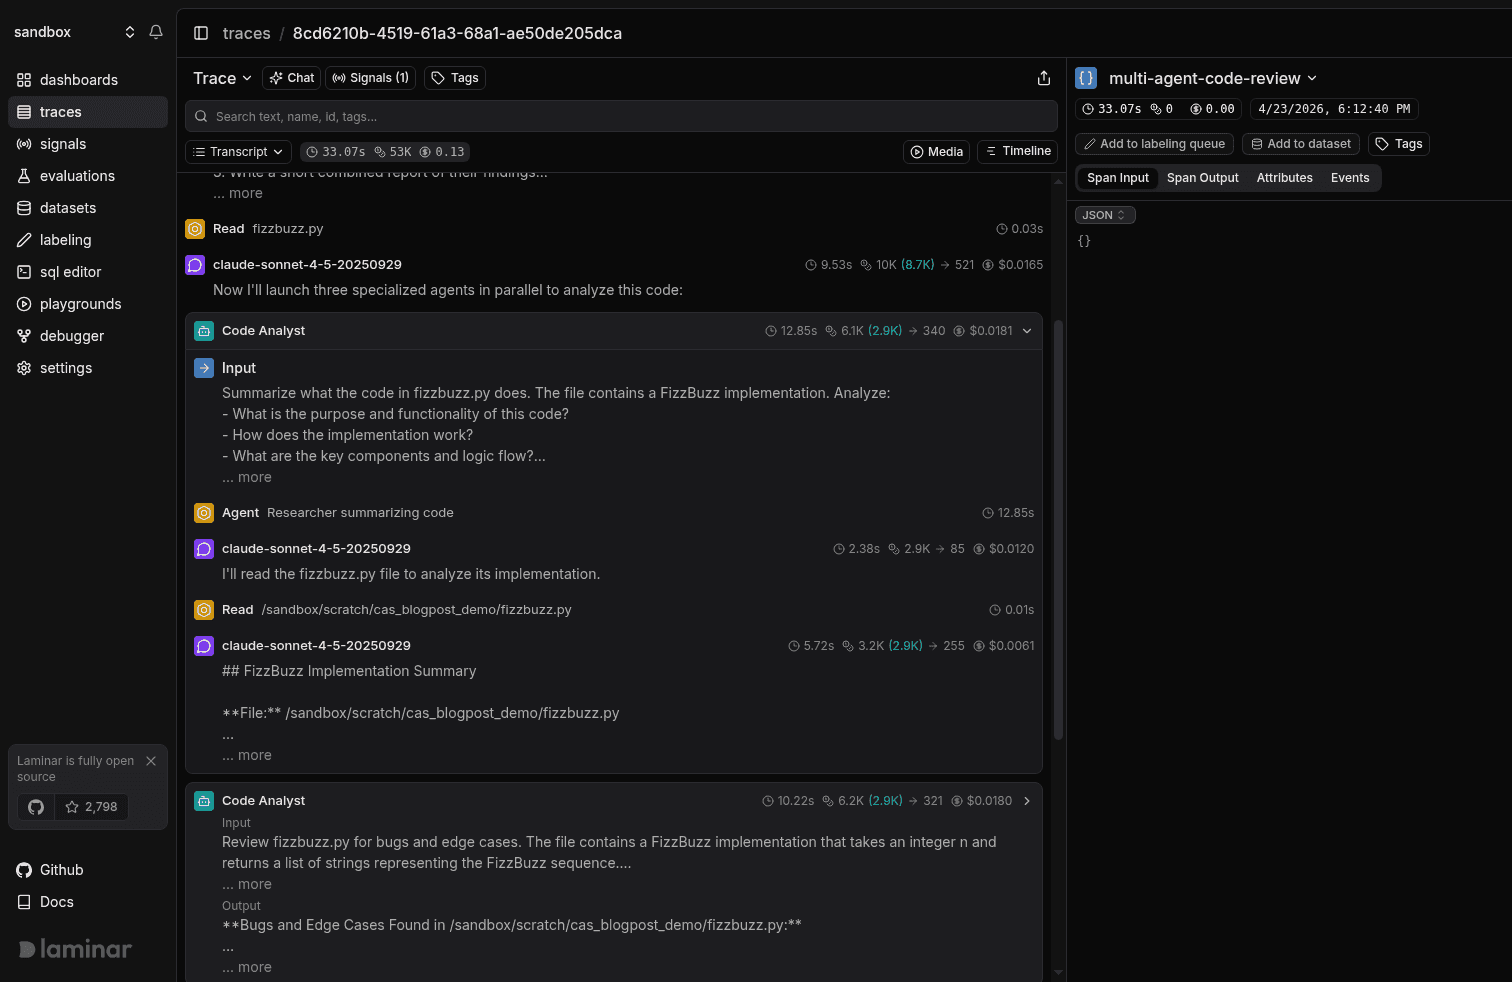
Transcript view of a 33-second, 53K-token, $0.13 run. The agent's input is extracted to the top without any code on your side, and each subagent is a card you expand in place.
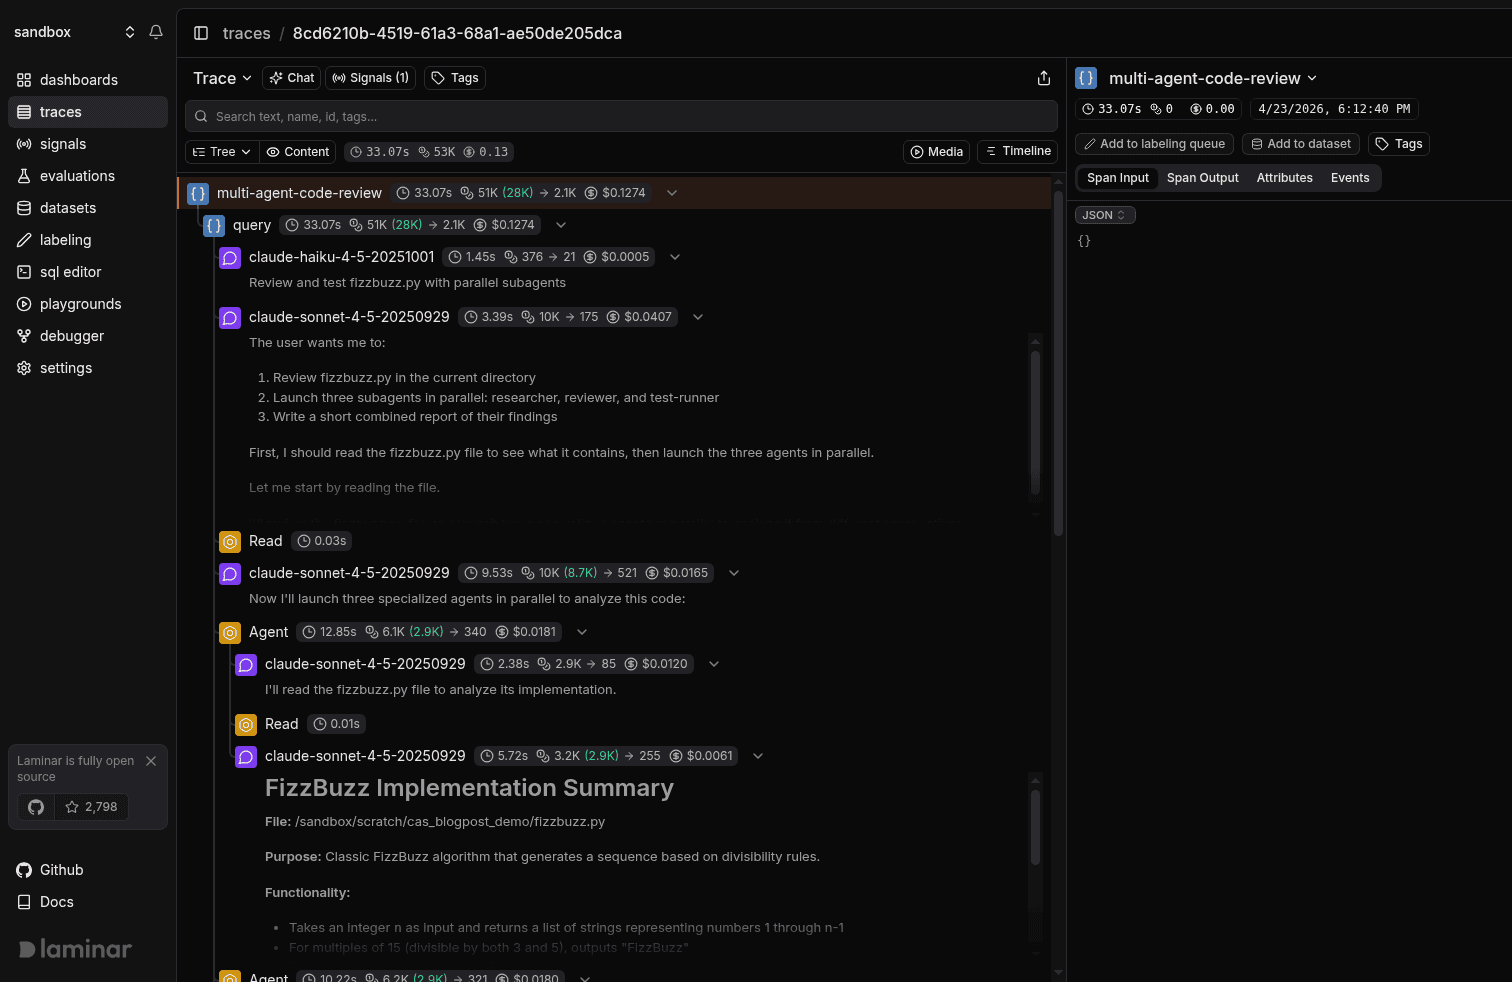
The same trace as a tree. Useful for "what took the time". Not useful for "what did the Code Analyst subagent conclude".
In Laminar the transcript is the default. Agent input is extracted to the top of every agent and subagent with no instrumentation on your side, subagents expand in place instead of navigating away, and LLM turns carry inline previews so a 400-span run is skimmable (viewing traces, why agent traces aren't backend traces).
Tracking multi-turn agents and sessions
A single trace is one run, and most real agents are not one run. A support agent handles twenty turns; a coding agent works a task across an afternoon. In both, the bug you are chasing usually started earlier than the run you are looking at.
Sessions group traces under one identifier, which gets you three things. The conversation as a unit, so you read turns 1 through 7 in order. Cost and token totals per conversation, which is the number that matters when you price per seat or per ticket. And drift you cannot see in one run: context growing every turn, a tool that worked at turn 3 and silently returns empty at turn 15.
Set the session ID to whatever your domain already calls a conversation: thread ID, ticket ID, task ID. Laminar takes it as one call on the trace and groups everything under it, cost included (sessions).
Detecting outcomes across runs: Signals
A trace answers what happened on this run. Across ten thousand runs the questions change: how often did the agent ask for clarification, how many runs hit the retry cap, what fraction of sessions ended with the user giving up.
You cannot answer those by reading traces, and tagging every span with every interesting outcome means deciding up front every question you will ever ask.
Signals are Laminar's answer. A Signal is an instruction in plain language plus a JSON schema for the structured output. Laminar runs it against every matching trace and produces one signal_event per match, linked back to the source trace and carrying the payload. On Laminar Cloud, each trace is investigated by the Signals agent running flow-1, our model for understanding agent traces, which is what makes covering every trace, not just a sample, affordable.
A worked example. The whole definition is this:
Detect when the agent asked the user for clarification. Extract: was_clarifying (bool), reason (string: what the agent was unclear about), resolved (bool: did the user provide what was needed).
No tagging, no schema migration, no code in the agent.
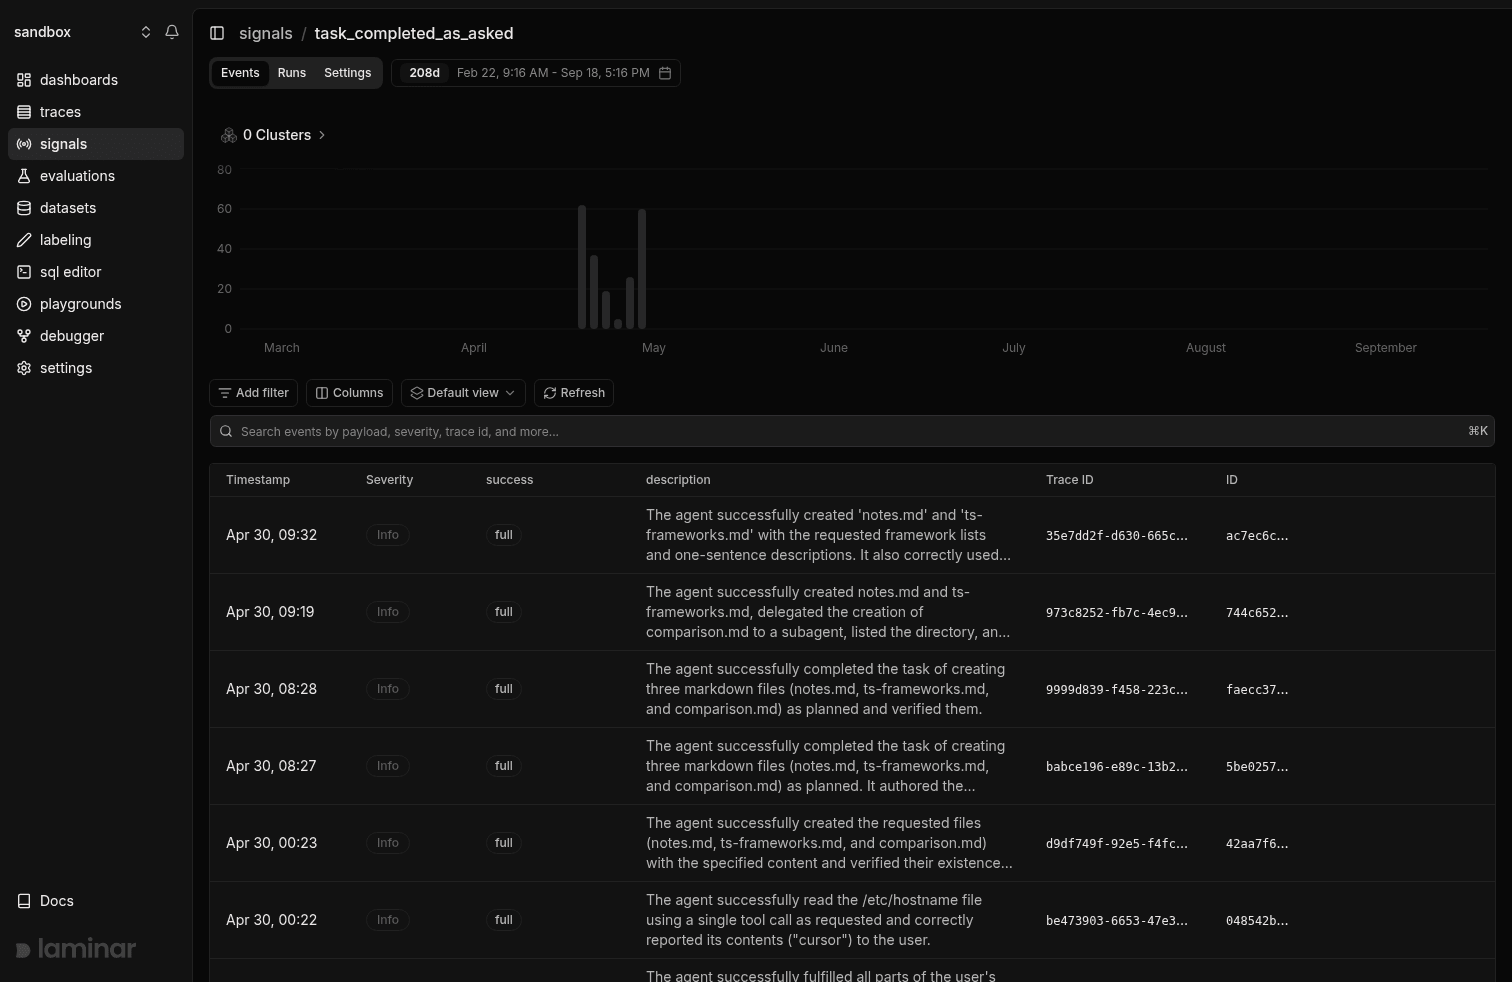
A signal is an instruction plus a JSON schema. Laminar extracts it from every matching trace and stores the result as a queryable structured event.
Signals run in two modes. Triggers fire on new traces as they arrive, which is what feeds live error rates and alerts. Jobs run across a historical window, so a Signal written today backfills against last week's traffic.
Both modes produce the same kind of event, queryable in SQL:
SELECT trace_id, count(*) AS clarifications
FROM signal_events
WHERE signal_id = '...' AND timestamp > now() - INTERVAL 7 DAY
GROUP BY trace_id
HAVING clarifications > 3
Similar events are auto-grouped into clusters, so the top ten failure modes are a list you read rather than an investigation you run.
Querying across traces with SQL
Dashboards answer the questions someone anticipated. The questions that matter during an incident are the ones nobody anticipated, which is the argument for a trace store you can query directly.
Cost by model over the last week:
SELECT model, sum(total_cost) AS cost, count(*) AS calls
FROM spans
WHERE span_type = 'LLM' AND start_time > now() - INTERVAL 7 DAY
GROUP BY model
ORDER BY cost DESC
Which operations fail, and how often:
SELECT name,
       countIf(status = 'error') AS errors,
       count(*) AS total,
       round(errors / total * 100, 2) AS error_rate
FROM spans
WHERE start_time > now() - INTERVAL 1 DAY
GROUP BY name
HAVING total > 10
ORDER BY error_rate DESC
Spans, traces, and signal events are all tables. Anything you can express as a query is available without waiting for a vendor to ship a chart, and a useful query pins to a dashboard (SQL editor).
From traces to evals: the improvement loop
Observability that ends at "here is what happened" is a read-only tool. The loop that actually improves an agent has four steps, and tracing is only the first.
1. Find the failure. Either a user reported it or a query surfaced it. Error rate by operation and outcome frequency per run catch most of it.
2. Read the run. Open the trace, read the transcript, find the turn where the agent went wrong. This is the step that is slow with the wrong tooling.
3. Reproduce and fix. Rerun the agent against the recorded run, so you are debugging the same input rather than a new one.
4. Prove it with an eval. One replay shows the fix works on one input. Turn the failing traces into a dataset, score the agent on it, and compare runs. Now "did this get better" has an answer that is not a vibe (evaluations).
The output of step 4 feeds step 1 again. Failing traces become test cases, test cases catch regressions, regressions show up as traces.
The debugger: rerun from any point in a trace
Step 3 is where the time goes, because reproducing an agent failure normally means running the whole thing again and paying for every LLM call to reach the one turn you care about.
Laminar's debugger replays a recorded trace instead. Set LMNR_DEBUG=true and point LMNR_DEBUG_REPLAY_TRACE_ID at the trace you are investigating, and the run re-executes your current code against the original input while serving the LLM responses from the recorded run out of cache. Turnaround drops from minutes to seconds, and because the responses are identical, a behavior change is your change rather than sampling noise.
Each run joins a session recorded in .lmnr/debug-session.json, so the whole investigation reads as one timeline. That file is also why a coding agent can drive the loop itself: rerun, read the score trend, iterate.
Self-hosted vs cloud agent observability
Trace data contains your prompts, your users' inputs, and your model outputs. For plenty of teams that decides the question on its own.
Cloud means no infrastructure: an API key, an SDK call, traces appear. You accept that prompts and completions leave your network, and you rely on the vendor's retention and access controls.
Self-hosted keeps everything inside your perimeter, which is usually what regulated or on-prem deployments require. You run and scale the backend and its storage, trading a subscription for infrastructure and operational time.
Two things to check either way. Whether the self-hosted build is the full product or a stripped-down community edition, because "open source" sometimes means a tracing viewer with the useful parts behind a cloud login. And whether ingestion is standard OTLP, so your instrumentation survives a change of mind.
Laminar is Apache 2.0 and self-hostable with Docker Compose or Helm, running the same ingestion path as the managed cloud. Tracing, full-text search, dashboards, SQL, evaluations, datasets, and the debugger are in the open-source build; Signals and its email and Slack alerts are the enterprise additions and need a license key (self-hosting, github.com/lmnr-ai/lmnr).
Common mistakes in AI agent observability
Tracing LLM calls and nothing else. A trace made only of LLM spans loses the tool calls, where most bugs are, and the structure, which is how you navigate.
Logging a summary instead of the content. "Called the model, 1,284 tokens" saves storage and destroys the point. When a run goes wrong, the exact text is the evidence.
No session ID on multi-turn agents. Every turn becomes an orphan and cross-turn bugs become invisible. Cheapest thing to fix, most commonly skipped.
Treating HTTP 200 as success. Agents fail successfully. If your only health signal is error rate, quality regressions stay invisible until a customer files a ticket.
Sampling aggressively in production. Standard APM advice, wrong here. The interesting runs are rare by definition, and a 10% sample drops 90% of them. Keep the errors and the outliers.
Collecting traces and never querying them. A trace store nobody queries is an expensive log. Production failures are also the best eval inputs you will get; if they are not flowing into a dataset, you are debugging the same class of bug on repeat.
Agent observability tools
The category splits three ways. General-purpose OpenTelemetry backends (Jaeger, Grafana Tempo, Honeycomb, Datadog) treat an LLM span as an ordinary span: strong on latency and error rates across a fleet of services, indifferent to what the model said. LLM-era platforms (Langfuse, LangSmith, Braintrust, W&B Weave) are built around the prompt and completion pair, which is the right object when your app is a chain and the wrong one when it is a thirty-minute run. Agent-focused tools are built around the whole run: transcript over span tree, replay, and outcome detection across traces rather than inside one. Arize Phoenix sits across two of these, OpenTelemetry-native with an evaluation-first workflow.
Which fits depends on your primary object. A request: your existing APM is probably fine. A prompt: an LLM-era platform will feel natural. A run that lasts minutes and fails somewhere in the middle: the third category.
For a feature-by-feature comparison, see Top 6 Agent Observability Platforms (2026): A Developer's Ranking.
FAQ
How is agent observability different from LLM observability?
LLM observability centers on the individual model call: the prompt, the completion, the tokens, the cost. Agent observability centers on the run: dozens or hundreds of calls, the tool calls between them, subagent boundaries, retries, and whether the run accomplished the task. Every agent observability tool includes LLM observability; the reverse is not true, and a prompt-logging tool will not show you why an agent looped.
Do I need OpenTelemetry for agent observability?
No, but it is the safest choice. OpenTelemetry is the vendor-neutral standard for traces, and a backend that ingests OTLP means your instrumentation is portable if you switch tools. A proprietary SDK works and is sometimes easier to start with, at the cost of re-instrumenting everything later. If you already run an OpenTelemetry collector, the incremental work is one exporter endpoint. Laminar accepts OTLP over gRPC, HTTP/protobuf, and HTTP/JSON on both cloud and self-hosted.
What should I instrument first in an AI agent?
Every LLM call and every tool call, wrapped in one top-level span per run that carries a user ID and a session ID. That gets you a readable trace and per-run cost on day one. Add retrieval spans and subagent boundaries next. Skip streaming token events and framework internals; they add span volume without adding answers. See Laminar's integrations.
How much overhead does agent tracing add?
Well-built instrumentation exports spans asynchronously in a background batch, so the agent does not wait on the network. The practical cost is serializing prompts and completions, small relative to an LLM call that takes hundreds of milliseconds. Measure it in your own setup rather than trusting a published figure, and flush explicitly in short-lived processes such as serverless functions so spans are not dropped at exit.
Can I self-host agent observability?
Yes. Several platforms ship a self-hostable build, usually required when prompts contain regulated data. Check two things: whether the self-hosted edition is the full product or a reduced community version, and whether ingestion is standard OTLP so you are not locked into one vendor's SDK. Laminar is Apache 2.0 and self-hostable with Docker Compose or Helm, running the same ingestion path as the cloud.
Last updated: September 2026.